An inference primer for Go engineers
Chapter 5 — Making the weights small
A model’s weights are the bulk of what it is. This chapter is about storing them in fewer bits, why that makes things faster for a reason people usually get wrong, and what “still correct” means once you’ve changed the arithmetic.
The problem
A model with 7 billion parameters, stored as 16-bit floats, is 14 GB. That doesn’t fit on a consumer GPU and strains a laptop. A 27B model at 16 bits is over 50 GB.
More importantly, every single one of those numbers has to be read from memory for every token you generate. Chapter 4 removed redundant computation; Chapter 4 did nothing about the fact that decode reads the entire weight set once per token.
That is the real constraint. Decode is memory-bandwidth-bound: the arithmetic units spend most of their time waiting for weights to arrive. If you halve the bytes, you nearly halve the time — not because there is less arithmetic, but because there is less waiting.
  a 7-billion-parameter model, read once per generated token

    16-bit floats   14.0 GB per token
     8-bit ints      7.0 GB per token
     4-bit ints      3.5 GB per token

  the arithmetic is identical in all three rows; only the traffic changes,
  and on a memory-bound workload the traffic is what sets the time
This is a familiar shape if you’ve optimized Go: the win comes from cache behaviour and memory traffic, not from instruction count.
Predicting the speed before measuring it
Because decode reads every weight once per token, its speed has a ceiling you can work out on paper, before running anything.
Each weight takes part in one multiply and one add per token, so a model with N parameters does about 2N operations per token. At 4 bits a weight is about half a byte, which is roughly four operations for every byte read. Processors can do far more arithmetic than that in the time one byte arrives from memory, so the arithmetic units wait. That is what “memory-bandwidth-bound” means in numbers, and it gives the ceiling:
  tokens per second  ≤  memory bandwidth  ÷  bytes read per token

  bytes read per token   =  weight bytes  +  KV-cache bytes at the current depth
  KV bytes per position  =  2 × KV heads × head dim × bytes per value × layers
                            (the 2 is one K and one V)
The KV term grows with the conversation. Qwen2.5-1.5B has 28 layers and 2 KV heads of dimension 128, so at 16-bit values it stores 28 KB per position, and at a 3,900-token context every new token reads about 110 MB of cache on top of the weights. That is a large part of why decode slows down as a conversation gets long. (These two figures are arithmetic from the model’s config, not measurements.)
Here is the ceiling next to what was measured, at short context, where the weights are almost all of the traffic.
The bytes are what goinfer actually streams per token at int4 with an 8-bit LM head, counted from its own kernels:
on the CPU 1,053 MB for the 1.5B (cpu-decode-roofline-2026-09-23.md),
and on Metal 970 MB for the 1.5B and 4,216 MB for the 7B, summed from each layer’s matrix-vector kernels plus the LM
head (metal-decode-gemv-s0-2026-09-26.md).
| machine, model | bandwidth | ceiling | measured | share of the ceiling |
|---|---|---|---|---|
| Ryzen 7 3700X CPU, 1.5B | 28–31 GB/s, measured by a read-only stream | 27–29 tok/s | 19.4 tok/s (2026-09-23) | about 70% |
| M1 Pro GPU, 1.5B | 200 GB/s on the spec sheet; 178–182 GB/s measured by a streaming read | 183–188 tok/s | 95.6 tok/s (10.46 ms of GPU time per token) | about 52% |
| M1 Pro GPU, 7B | the same | 42–43 tok/s | 30.2 tok/s (33.12 ms) | about 71% |
The GPU rows are GPU time per token, taken from the command buffers’ timestamps, so a served request adds a little
host time on top (metal-decode-gemv-r18b-2026-09-26.md).
The ceiling tells you the best case, not where you are. Before September 26 the 1.5B’s token took 12.93 ms on the
GPU. Its int4 matrix-vector kernels moved weights at 64–111 GB/s (the largest, gate/up, at 90 GB/s), while a kernel
doing the same loads and nothing else reached 176–187 GB/s on the same shapes, and the 8-bit LM head, which does less
work per byte, ran at 161 GB/s (metal-decode-gemv-s0-2026-09-26.md).
So the bytes were not the limit; the work done on each weight was: unpacking the 4-bit values, applying their scales
and accumulating. Rewriting those kernels in the shape MLX uses, several rows per SIMD group, took gate/up to 115–140
GB/s and the token to 10.46 ms, with bit-identical output
(metal-decode-gemv-r18-2026-09-26.md). The bandwidth
did not change. The kernel got closer to it.
The same reading explains the CPU row. There Ollama moves its bytes at 23.5 GB/s on the 1.5B against goinfer’s 20.4, while goinfer actually streams 7.5% more bytes per token. The gap is in how close each gets to the ceiling, not in the format. Arithmetic gives the ceiling; only a measurement shows how far from it you are, and why.
Quantization
Store each weight in fewer bits. Instead of a 16-bit float per number, use 8 bits, or 4.
The mechanism is scaling. Take a block of weights — say 32 or 64 weights — find the largest magnitude in the block, and store a single scale factor for the block plus a small integer per weight. To use a weight, multiply that weight’s integer by the block’s scale.
  storing:    scale = max|w| / 7            (7 = largest 4-bit signed int)
              int[i] = round(w[i] / scale)

  using:      w[i] ≈ int[i] × scale

  worked, with a block whose largest magnitude is 0.021:

    scale = 0.021 / 7 = 0.003

    w        w / scale      stored int    reconstructed
    +0.021     +7.00            +7           +0.021      exact
    −0.019     −6.33            −6           −0.018      off by 0.001
    +0.008     +2.67            +3           +0.009      off by 0.001

  the rounding error is the accuracy cost, and it is bounded by half a
  scale — which is why the block's largest magnitude sets the precision
  for every weight in that block
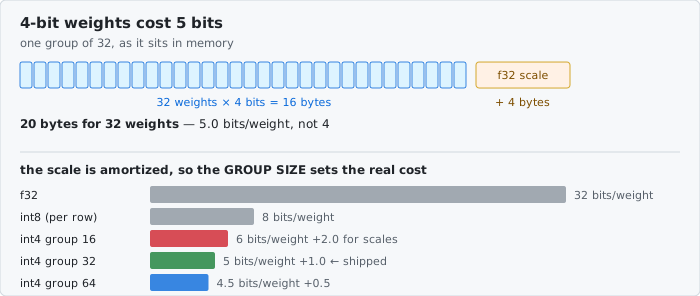
Block size is the tuning knob. Smaller blocks track local variation better and cost more scale factors; larger blocks are more compact and lose more precision where one block spans very different magnitudes. Note that the scale factors are themselves stored, so a “4-bit” format costs slightly more than 4 bits per weight in practice.
The naming you’ll see: int8 is 8 bits per weight, int4 is 4. A suffix like int8int8
means both the weights and the activations flowing through them are 8-bit. q4_k_m is
llama.cpp’s naming for one particular 4-bit scheme, and goinfer reads those files.
The counter-intuitive result
The obvious expectation is that int4 is faster than int8 — half the bytes — but less accurate, and that you would pick between int4 and int8 based on how much quality you can spare.
On Apple Silicon CPU decode in this repo, that expectation was wrong for a while, and then the expectation became right for an interesting reason.
Measured after a fix to how the LM head is quantized:
| model | int4 | int8int8 |
|---|---|---|
| 0.5B | 81.9–83.75 tok/s | 85.25 tok/s |
| 1.5B | 39.1–40.7 tok/s | 37.56 tok/s |
int4 now matches or beats int8int8’s speed at both sizes. RAM is the opposite story on Apple
Silicon: the loader keeps a second, repacked copy of int4’s nibbles alongside the canonical ones
for the fast NEON kernel, so int4 actually costs more resident RAM there than int8int8, not
less (decoder/fitguard.go). The current guidance in
docs/benchmarks.md is
that int4 is the right default on Apple Silicon CPU decode for speed — reach for int8int8 instead
if RAM, not speed, is the binding constraint.
What is instructive is what docs/benchmarks.md does with the old advice, which said the
opposite. The old advice is not deleted. The old advice is kept, marked superseded, with the
reason recorded: the old advice was a correctly-diagnosed reading of the machine at the time,
and the thing the old advice was measuring around — the LM head’s drag on the int4 path — no
longer exists. The advice changed because the code changed, not because the earlier
measurement was wrong.
That is the repo’s convention and Chapter 11 explains why it matters. A superseded number that quietly disappears leaves the next reader unable to tell whether it was wrong or whether the world moved.
What “still correct” means
You changed the arithmetic. The model now computes with different numbers than the reference implementation does. So in what sense is it the same model?
Two answers, and this repo uses both.
Numerical parity against HuggingFace. The reference is the same checkpoint running in
Python. goinfer’s forward pass is gated against the Python reference, and there is a parity
runner in cmd/gate for exactly that comparison. Quantization is expected to move the numbers
slightly; the parity gate establishes how much the numbers move, and establishes that the
deviation stays within a stated tolerance rather than drifting.
Bit-identical decode. For a fixed quantization and a fixed seed, goinfer produces exactly the same tokens every time. Bit-identical decode is a determinism claim, not an accuracy claim — bit-identical decode says the engine is reproducible, which is what makes every other test in the repo meaningful.
The distinction matters for what you may and may not do. Quantizing weights is a stated, measured accuracy trade the user opts into by choosing a checkpoint format. Quantizing the KV cache, as Chapter 4 mentioned, interacts with the determinism contract differently — which is why it is treated as a separate decision rather than an obvious extension.
Formats, briefly
Quantization schemes ship inside checkpoint files, and goinfer reads several:
- safetensors — HuggingFace’s format, usually 16-bit, sometimes pre-quantized
- GGUF — llama.cpp’s format, carrying its own quantization schemes and its tokenizer
- GPTQ / AWQ — quantization methods that use calibration data to decide where precision matters most, rather than treating every block identically
- .giw — goinfer’s own pre-quantized bundle format, so the quantization work happens once rather than at every load
Reading GGUF matters practically: GGUF is what most locally-available quantized models are distributed as. Reading safetensors matters because safetensors is what models are published as, so goinfer can run a checkpoint on release day without waiting for someone to convert that checkpoint.
What it costs
Quantization is close to free in the sense that matters: it makes decode faster and models smaller, at an accuracy cost small enough that 4-bit is a reasonable default.
The number worth carrying: int4 halves the weight memory against int8 and, on Apple Silicon CPU decode, gives equal or better throughput. That combination is why it’s the default there.
What quantization does not fix is a model that does not fit at all. A 27B model at 4 bits is still over 15 GB, which fits neither of this repo’s development GPUs. Chapter 6 is about what you do when the model does not fit.
Try it
Ask fit (Chapter 4’s command) for the 1.5B at 8-bit weights:
goinfer-chat fit hf:Qwen/Qwen2.5-Coder-1.5B-Instruct-GGUF:q4_k_m -quant int8int8
The CPU row reads dense 1.66 GB: every weight at one byte, plus its group scales and the embedding table. The default
4-bit load is much smaller; fit prints that too, but from whichever converted copy of the model your machine has
cached, so the exact figure depends on what you ran before (the record explains). Measured on 2026-10-02 with the
v0.20.0 release (record, chapters 4 and 5).
Sources: docs/benchmarks.md §int4/int8int8 comparison, docs/completed/task-w4a8-neon-bandwidth.md,
cmd/gate (parity runner), docs/api-tiers.md (.giw).